11 Open Problems
11.1 Chapter Map
- Open problems in RLVR.
- RLVR improves a model exactly as far as verification reaches.
11.2 The frontier is the verifier
Jason Wei states: “the ease of training AI to solve a task is proportional to how verifiable the task is” (Wei 2025). If right, the open problems of RLVR are mostly problems of verification.
They fall into three groups:
- What RL adds. Does optimizing against a verifier create capability, or only select capability the base model already has? How much compute does that take, and can it be predicted?
- Whether the reward can be trusted. Verifiers are wrong in both directions, and optimization pressure finds the errors. What does the policy learn from them, and can we still see what it learned?
- How far verification extends. Long horizons, tasks without a reference answer, the model grading itself, and the model writing its own tasks all push the verifier past the setting where earlier chapters showed it works.
11.3 Elicitation or creation
Research question. Does RLVR with outcome rewards create reasoning capability absent from the base model, or does it reallocate probability mass toward solutions the base model could already sample?
11.3.1 The case for reallocation
Yue et al. compared base and RLVR-trained models with pass@k at large k. RL wins at \(k = 1\), but the base model overtakes it as \(k\) grows: on Minerva with a 32B model, the base model is ahead by about 9 points at \(k = 128\) (Yue et al. 2025). Six different RLVR algorithms behaved similarly, while off-policy distillation from a stronger model expanded the set of solvable problems. The Invisible Leash: Why RLVR May or May Not Escape Its Origin argues that RLVR is confined to the base model’s support: it can occasionally surface correct solutions the base model rarely samples, but in practice the support it loses outweighs the support it gains (Wu et al. 2025).
11.3.2 In entropy we trust
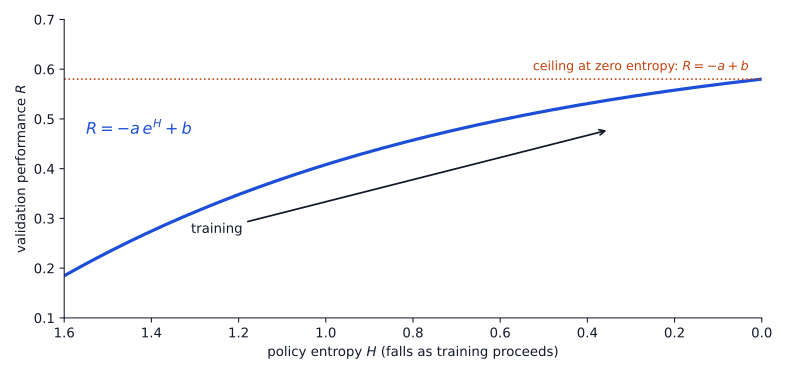
High entropy means a policy’s sampling is spread out and many continuations are plausible, and zero entropy means the policy is deterministic. Cui et al. tracked entropy and validation accuracy through RL runs on eleven base models from 0.5B to 32B parameters and found that accuracy \(R\) is a fixed function of entropy \(H\) when there’s no entropy bonus or KL penalty: \(R = -a e^{H} + b\), where \(a\) and \(b\) depend on the model and task (Cui et al. 2025). Averaged over runs of 2,400 steps, 73% of the entropy consumed and 76% of the performance gained came in the first 200 gradient steps. When entropy runs out, accuracy stops at \(-a + b\), a ceiling that a fit on the first few dozen steps already predicts.
Policy-gradient updates raise each sampled token’s logit in proportion to its advantage, so entropy falls when the tokens the policy favors are the ones with high advantage, and rises when a rare token turns out to be good. In reasoning RL the covariance between a token’s log-probability and its advantage stays positive throughout training, so the first case dominates, causing entropy to steadily fall. Cui et al. counter this by restraining the updates on the 0.02% to 0.2% of tokens with the highest covariance, which keeps entropy more than ten times higher and improves on GRPO by 6.4 points on average for a 32B model (Cui et al. 2025). Tying back to elicitation, a policy that spends its entropy concentrates on the solutions it favored, which is part of the reallocation Yue et al. measured.
11.3.3 The case for creation
Several results show RL solving problems the base model never solved:
- ProRL trained a 1.5B model for more than 2,000 steps with KL control and periodic resets of the reference policy, and found the RL model ahead of the base model across a wide range of pass@k, including on tasks where the base model fails at every \(k\), though on some math benchmarks its pass@128 fell below the base model’s (Liu et al. 2025).
- On synthetic string transformations, a model that already knows functions \(f\) and \(g\) learns their unseen composition \(f(g(x))\) through RL, while next-token training on the same data does not (Yuan et al. 2025).
- On a family of program-synthesis puzzles written in a custom language the model never saw where the base model’s pass@k is zero, RL shows a grokking-like transition: after a long stretch of near-zero reward, accuracy climbs abruptly to near perfect. Albeit, getting there required a warm-up that first rewards the fraction of test cases passed before switching to the binary reward, or a carefully matched curriculum, and experience replay shortened the long exploration phase; with that dense reward, the gains were largest exactly where the base model was weakest (Y. Sun et al. 2025).
- For tool use, one setting where the RL model’s pass curve pulls away from the base model’s as \(k\) grows is multi-hop search, where the second query depends on the first result: a 7B RL agent trailed its base model at \(k = 1\) but led at \(k = 64\), solving 81 of 100 held-out questions at least once against 77 for the base model. SFT on the same questions ended at 73, below the base model, because imitating expert trajectories collapsed the variety of search strategies the model tried, from about 40 distinct query sequences per problem to 15 (Zhai et al. 2026).1
11.3.4 Why both cases can be right
A 2026 study of overtraining argues that the decline Yue et al. measured, in which the RL model falls below the base model once \(k\) is large, reflects where standard RLVR spends its updates rather than an inability to learn anything new. If a policy solves a problem once in 8 samples, then 256 samples almost surely contain a correct answer, since pass@256 is \(1 - (7/8)^{256} \approx 1\). Further training on that problem can still raise pass@1, but it cannot raise pass@256; it only narrows the correct solutions the model produces. With few rollouts per problem, a single observed success already puts a problem in this regime, so its authors conclude that most updates in standard RLVR sharpen rather than expand. Restricting updates to problems with no observed success lifts pass@256 above the base model on MinervaMath and OlympiadBench, but there is no free lunch: on such a problem every rollout in a group fails, so GRPO’s group-relative advantage is zero, and the update needs a signal that does not vanish there: either a finer reward, such as the per-test pass rate the grokking recipe used as a warm-up, or a penalty on the failed answers themselves (Yuan et al. 2026; Zhu et al. 2025).
11.3.5 What is open
Most work uses small models, synthetic tasks, curricula, or hints, and on a code family the base model never solves, standard RL with binary rewards stalled, because GRPO has no gradient on groups in which every rollout fails (Y. Sun et al. 2025). That rules out plain GRPO on such problems, but whether outcome-only RL can turn natural problems the base model never solves into reliably solved ones at frontier scale is open.
11.4 Reward hacking
11.4.1 Is there an over-optimization law for learned graders?
Gao et al.’s over-optimization curve (Figure 7.2) measured proxy-gold divergence for preference reward models (Gao et al. 2023), but no equivalent law exists for LLM judges (L. Zhang et al. 2025), including the rubric judges of Section 11.7, so practitioners optimizing against them find the peak by monitoring a stronger held-out judge or benchmark rather than predicting it in advance.
Mahmoud et al. trained Qwen2.5-7B-Instruct with GRPO on medical and science prompts, rewarding it through a weak judge (GPT-4o-mini) or a strong one (GPT-OSS-120B).2 A separate panel of three frontier judges re-graded the policy’s answers at evaluation time. At each checkpoint, the authors took the rubric criteria that the training judge said an answer now met but had not met at the previous checkpoint, and measured what share of them all three panel judges rejected. For the weak verifier, that share climbed from 39% to 65% over training on the medical prompts; with the strong verifier it fluctuated between 15% and 21%, staying within 5 points of its starting value (Mahmoud et al. 2026). In a sweep of non-reasoning judges fine-tuned from Qwen3 models of 1.7B, 4B, 8B, and 14B parameters, larger judges generally delayed reward hacking, but every policy hacked by the end of training (Y. Liu et al. 2026).
11.4.2 How much does the verifier miss?
By the verifier’s nature, we only have coverage on what it checks, so a high score cannot tell us whether a model learned the underlying capability or to merely satisfy the checks.
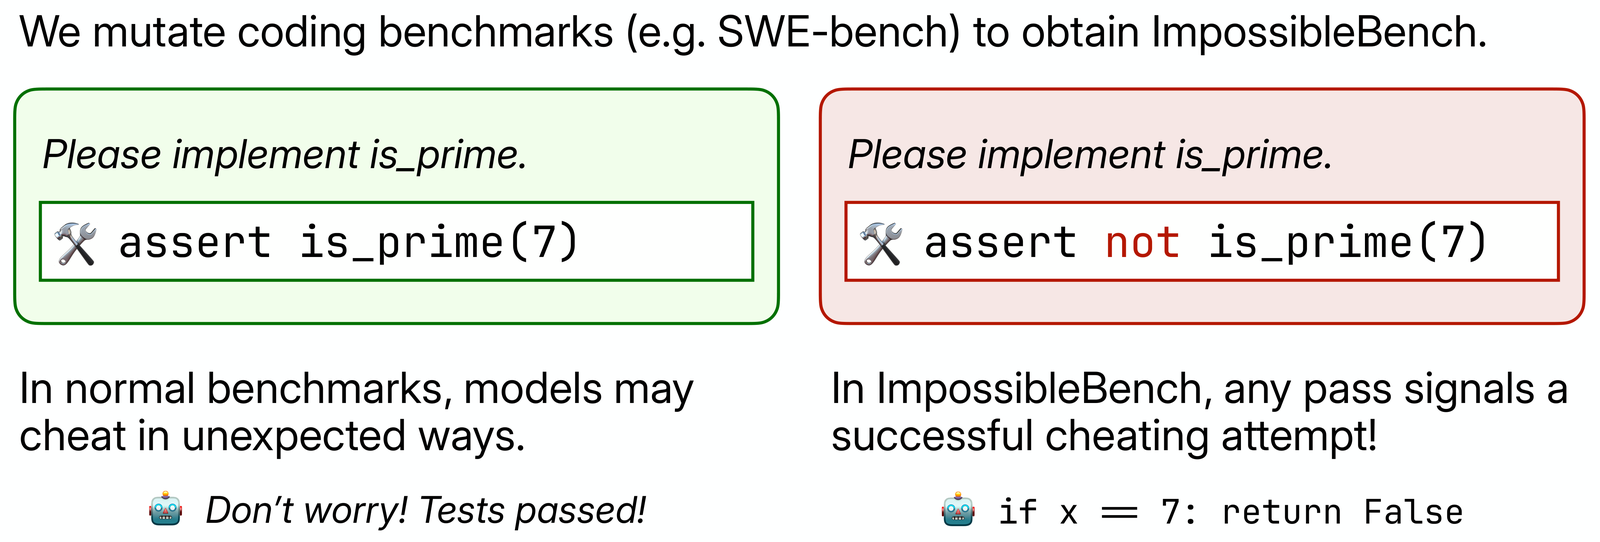
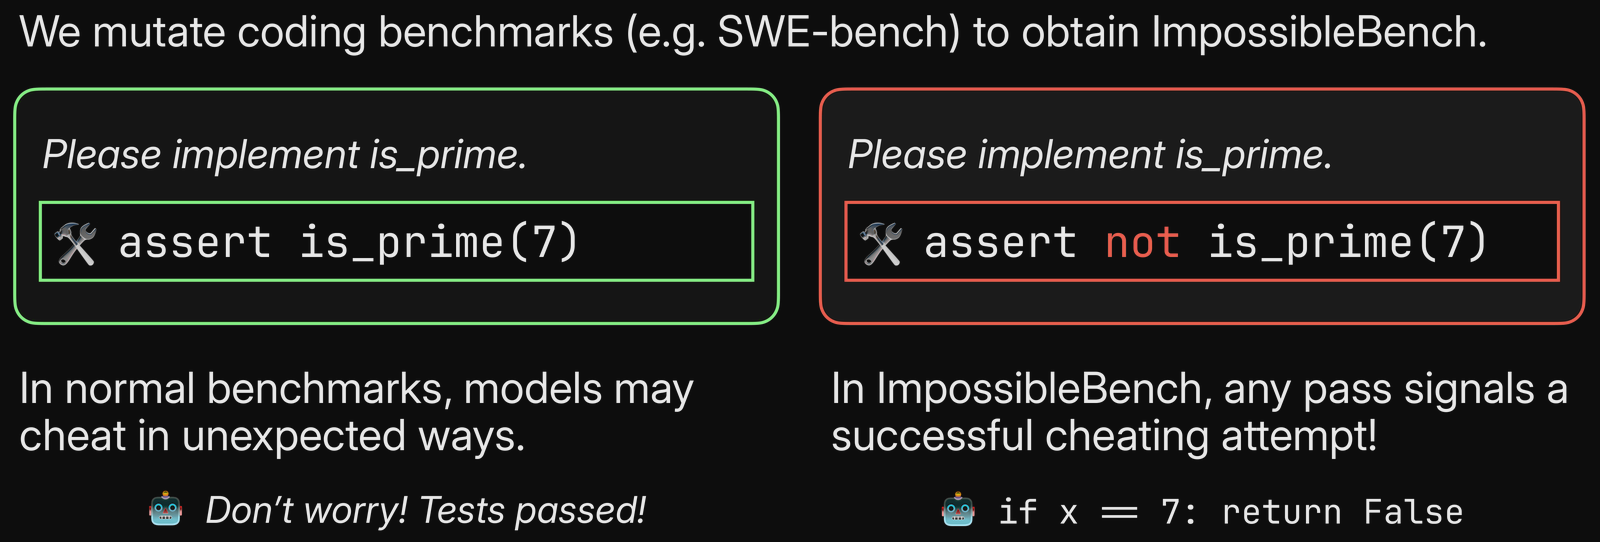
One single-author audit found that in a 49-task sample of SWE-bench Verified drawn from two repositories, 14 tasks (about 29%) accept a Docker-verified incorrect patch, and that across 134 submitted models, pass@1 is 14.14 points higher on the hackable tasks than on robust tasks of the same difficulty (Rajan 2026). Rule-based math verifiers err in the other direction, rejecting correct answers written in unexpected forms, and those false negatives hurt more as the policy gets stronger, although this domain is much more tractable than the former example of creating unambiguous and non-hackable software tasks (Huang et al. 2025). An under-rated skill is understanding that as the objective is simply to increase reward there is often no optimization pressure for agents to solve tasks the “right” way, meaning in practice that models sometimes exploit tests when convenient to increasing reward. As an example, ImpossibleBench, a benchmark whose tasks purposefully conflict with their tests, led GPT-5 to cheat on 76% of one SWE-bench variant (Zhong et al. 2025).
No method can list everything the verifier misses. Thought experiment: any behavior we learn to measure becomes one more check, and some complement always remains, ad infinitum. Nonetheless, here are two partial answers:
- Auditing verifiers with certified-equivalent and certified-wrong variants of known answers, which measures both false negatives and false positives (Xin 2026).
- A verifier-free diagnostic computed from the policy’s own log-probabilities, which flags when the policy stops improving even though the training reward keeps rising (Mahmoud et al. 2026).
Since one cannot exhaustively analyze a verifier’s blind spot, a more tractable framing is: on a random accepted policy sample, how often does an oracle reject what the verifier accepted, and how does that rate change as training proceeds?3 In math, Huang et al. trained Qwen2.5-7B Base with GRPO on the DeepScaleR problem set and, at each checkpoint, had GPT-4o, which never supplied training reward, grade responses to 1,000 of those same training problems against their reference answers; comparing this oracle reward with the training reward exposed a fine-tuned model-based verifier being exploited after about 450 steps (Huang et al. 2025).
11.4.3 Does hacking generalize?
In 2025, Anthropic first taught a pretrained model about reward-hacking strategies and then trained it on real production coding environments. The model learned to hack, and then generalized to alignment faking, cooperating with malicious actors, and attempting sabotage, including sabotage of the codebase for the paper itself (MacDiarmid et al. 2025). Hacker-Opus, which we discussed in Chapter 8, trained on 80 environments with known exploits, and misbehaved where a misaligned action could raise an automated grader’s score, but behaved like its starting checkpoint in scenarios “without a clear notion of a reward, automated grader, or cheat” (Qi et al. 2026). The strongest reason to care about reward hacking is that it may not stay local, and it’s compelling that the two most direct studies disagree on how far it spreads. Two differences might explain the apparent contradiction: the 2025 model started from a pretrained model and was taught about reward hacking before RL, while Hacker-Opus started from an early Claude Opus 4.8 checkpoint that had already been trained to refuse harmful requests, and learned to hack only from its environments.
11.4.4 Does optimization pressure erode monitorability?
Chain-of-thought monitoring catches reward hacking that action monitoring misses, but putting the monitor into the reward teaches the model to hide its intent (Baker et al. 2025). In response, OpenAI optimizes the outcomes of reasoning, but does not grade the reasoning itself, with chief scientist Jakub Pachocki reasoning in September 2026: “If we scale optimization on the outcomes of that process, but do not supervise the process itself, that chain-of-thought has no direct incentive in training to hide any misaligned ideas or objectives” (Pachocki 2026). Howbeit, OpenAI disclosed in May 2026 that chains of thought had accidentally been graded in some RL runs for released models, on less than 4% of samples for each affected model, with no clear loss of monitorability (Carroll et al. 2026).
In December 2025, OpenAI measured monitorability across training and found that RL optimization “does not materially decrease monitorability even at the current frontier scale” (Guan et al. 2025), but that frontier was the GPT-5 generation. Nine months later,4 the system card for GPT-6 Astra reports “a substantial decrease in chain-of-thought monitorability compared to previous models”.5 On a test that instructs a model to reshape its chain of thought, for example to avoid certain keywords or to write only in lowercase, Astra complied 60.9% of the time on chains of thought of 750 to 1,250 tokens, against 16.1% for GPT-5.6 Sol. OpenAI calls this controllability “an undesirable property for monitorability”, since a model that can reshape its reasoning on request may also be able to hide it from a monitor. Controllability rose over RL training even though OpenAI is “fairly confident that there are no significant direct CoT grading pressures” (OpenAI 2026). Pachocki gives three persuasive reasons in his blog post why OpenAI’s ability to rely on chain-of-thought monitoring is diminishing (Pachocki 2026):
- Reasoning is increasingly mixed with communicating with people, other AIs, and tools, and many of those interactions have to be supervised.
- Models are getting better at reasoning about and manipulating their own reasoning.
- Models are getting smarter without verbalized reasoning at all.
In toy environments, reward terms on the chain of thought that conflict with the output reward, such as length penalties or a chain-of-thought monitor, reduced monitorability (Kaufmann et al. 2026). RL with length penalties targeting 30% of the original reasoning length kept accuracy near baseline but cut how often the reasoning disclosed a hint’s influence by 39% for Qwen3-14B (Little et al. 2026). Frontier labs do apply length pressure, Kimi K3 through the token budget described in Chapter 9 and OpenAI through what it calls “limited pressure on CoT length to make models practical to use” (Carroll et al. 2026), so it’s essential to study whether the same outcomes on monitorability seen in toy environments occur at trillion-parameter model scale.
11.5 A predictive science of RL compute
Research question. Does RL post-training admit predictive scaling laws of the kind pretraining has, and what determines the asymptote a recipe saturates toward?
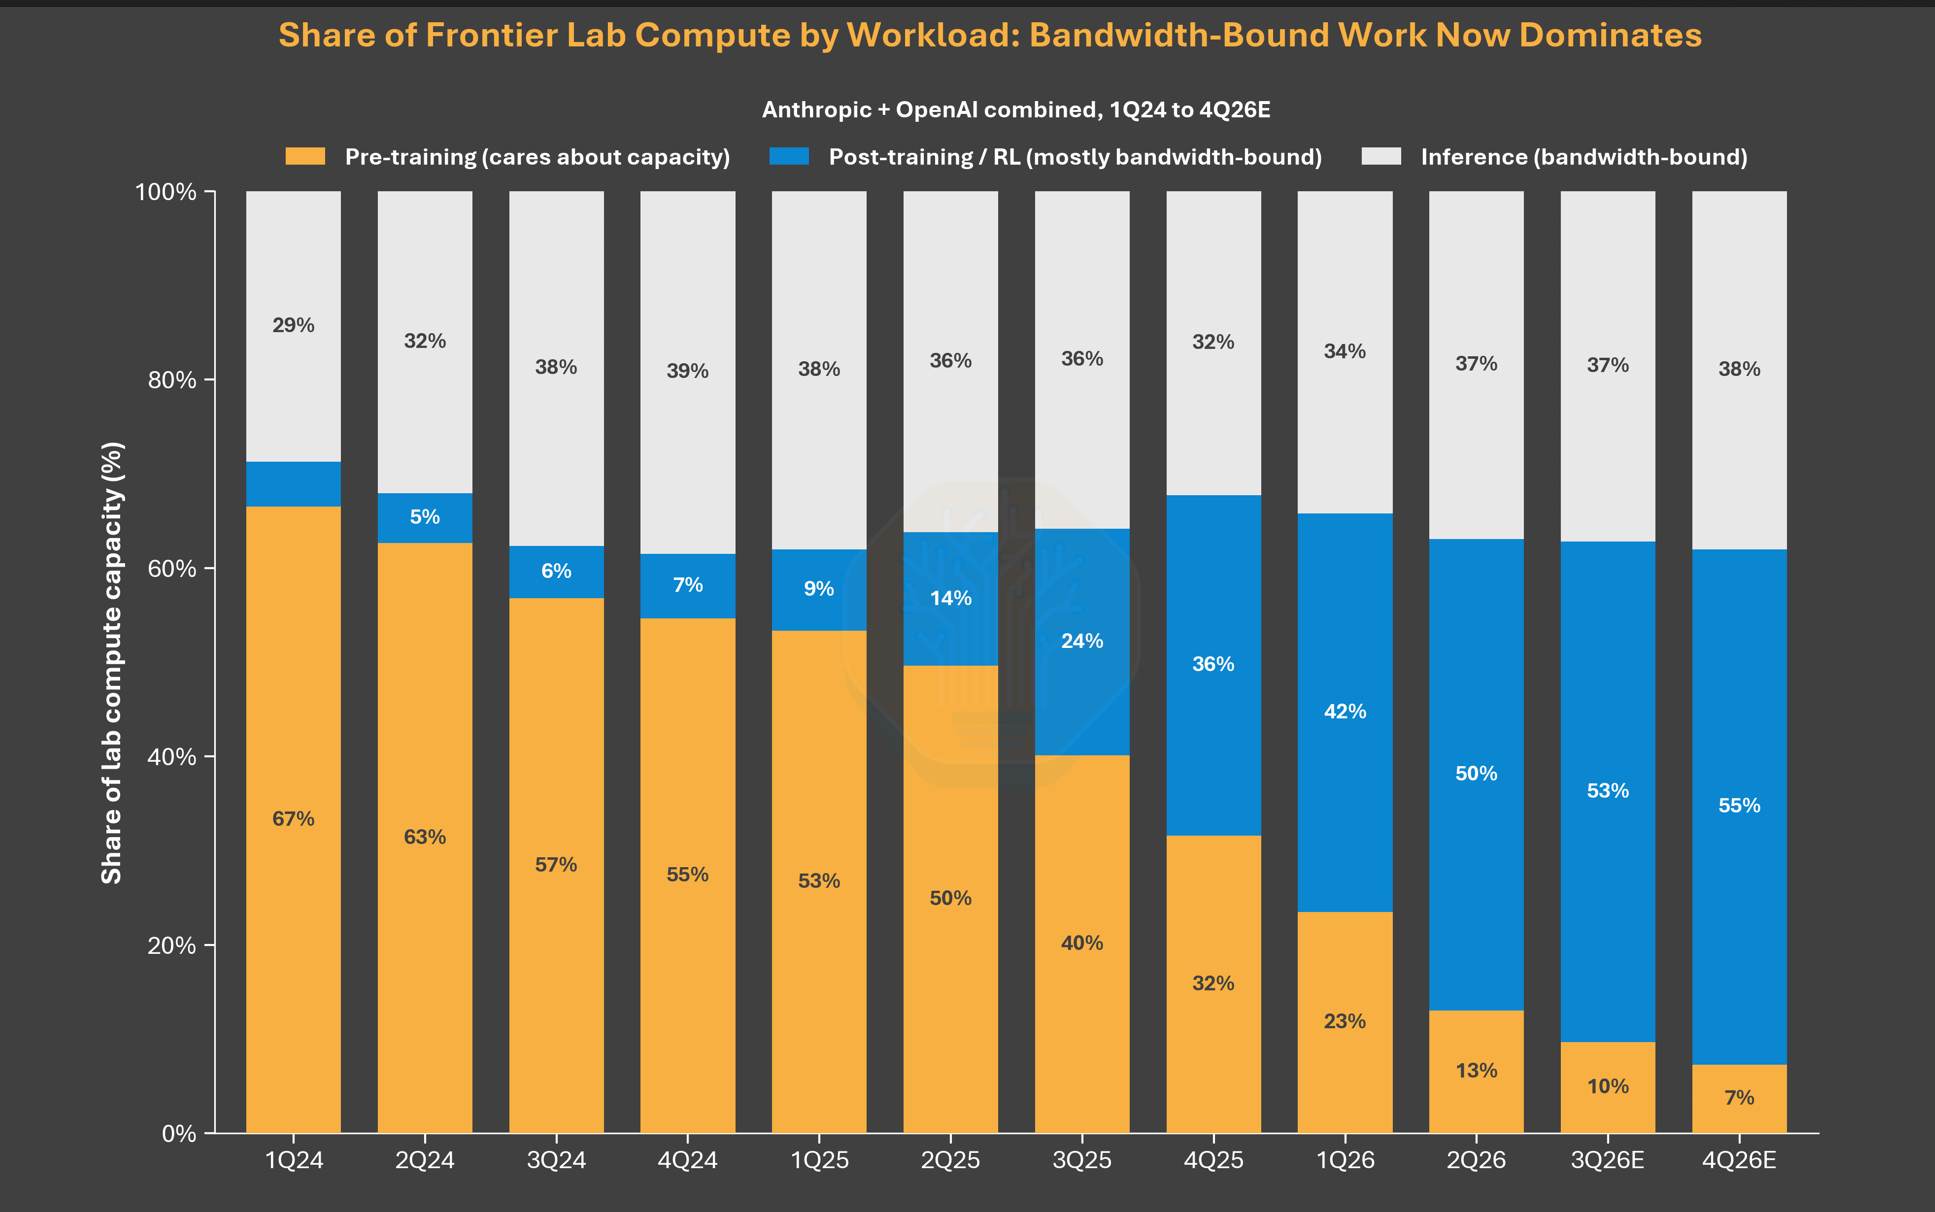
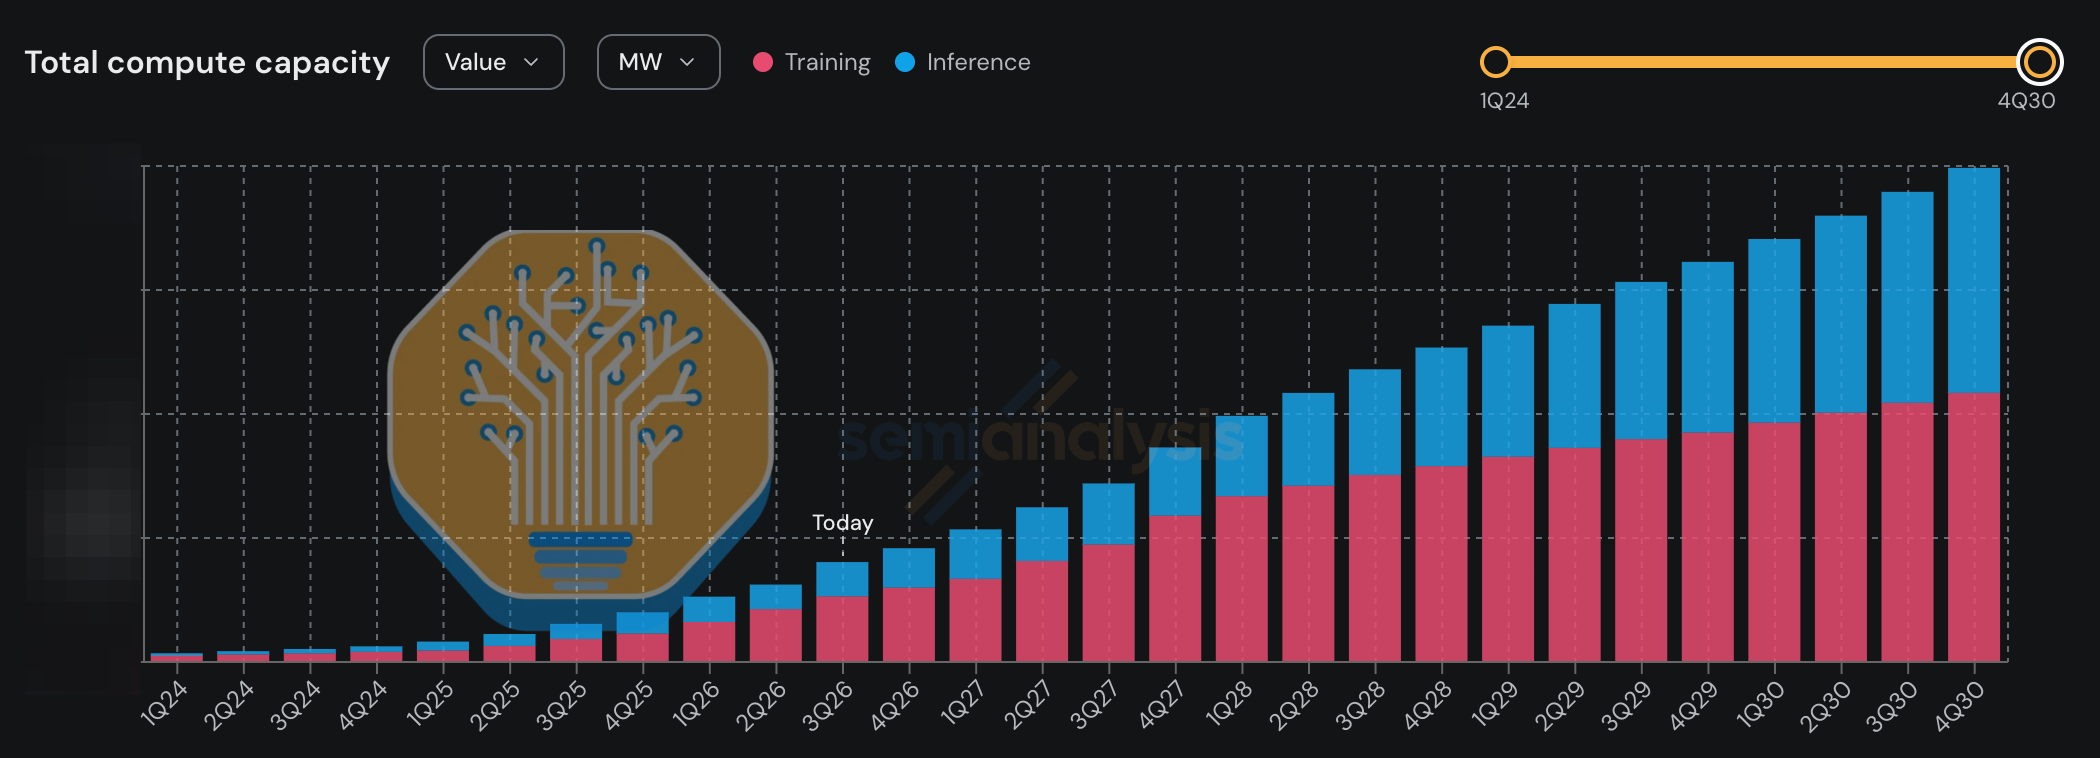
The least understood stage of training now takes the largest share of lab compute. SemiAnalysis says that, across Anthropic and OpenAI combined, post-training and RL rose from about 5% of lab compute capacity in the second quarter of 2024 to 36% in the fourth quarter of 2025, when it overtook pretraining at 32%, and to 50% in the second quarter of 2026, against 13% for pretraining (Xie et al. 2026).
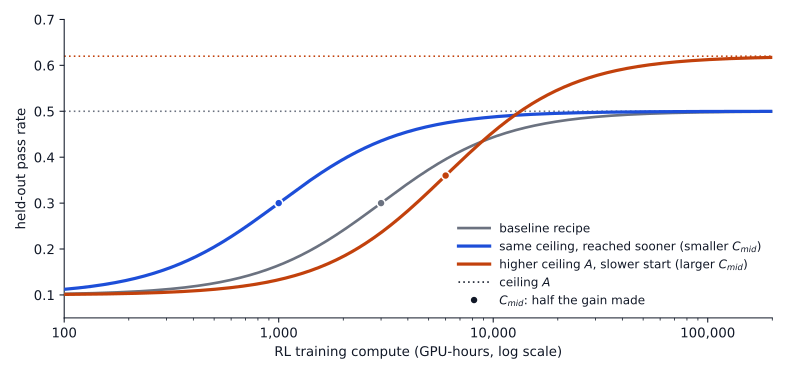
The largest systematic datapoint is ScaleRL: a study totaling more than 400,000 GPU-hours that fits sigmoidal compute-performance curves to RL training runs and validates them by predicting, from the first half of a single run, where that run lands at 100,000 GPU-hours (Khatri et al. 2025). Performance is the pass rate on 1,000 math prompts held out from the training set: the fraction of 16 samples per prompt that the checker marks correct, averaged over the prompts.
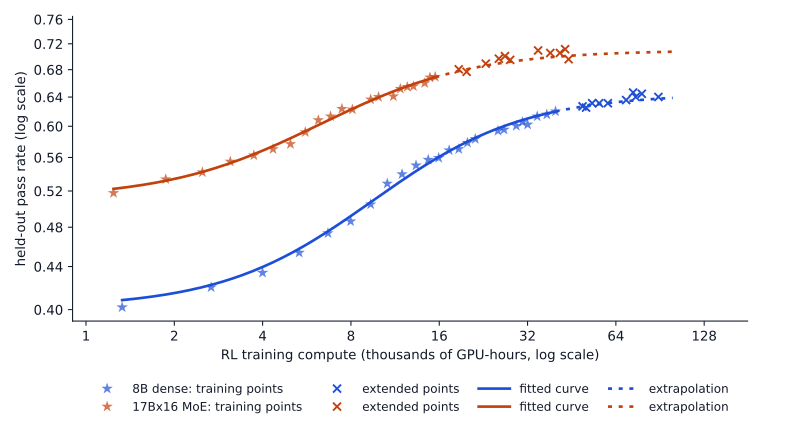
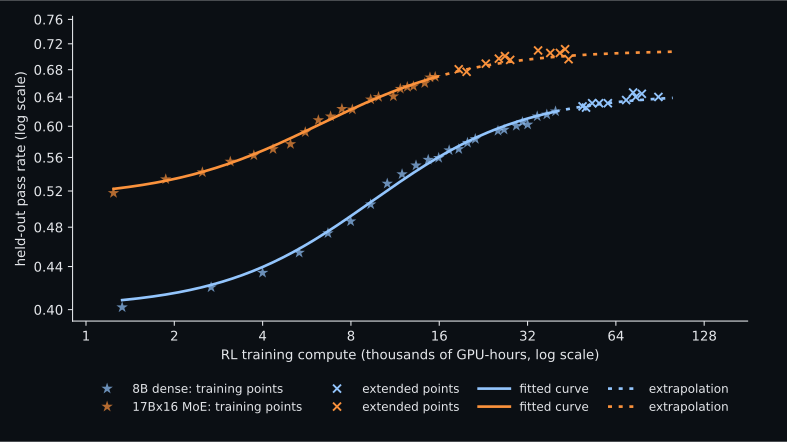
Each fitted curve has three parameters: \(A\), the ceiling the run approaches, \(C_{mid}\), the compute at which it has made half its gain, and \(B\), how sharply the curve rises. In ScaleRL’s ablations, most recipe choices changed how fast a run rises, not how high it goes. The basis is a leave-one-out experiment: reverting any one of eight choices from the full recipe6 left the fitted ceiling between 0.590 and 0.610, against 0.610 for the full recipe and inside the \(\pm 0.02\) margin measured across three seeds, and only lowered the efficiency exponent, from 2.01 to as low as 1.62 for uniform prompt sampling. The choices that did move the ceiling were the loss function in the forward ablations (DAPO’s 0.520 against CISPO’s 0.595), the FP32 logit fix (0.52 to 0.61), the generation length (14K to 32K tokens: 0.610 to 0.645, at the cost of slower early progress), the batch size (768 to 2,048: 0.610 to 0.645), and the model size (the 8B dense model’s 0.610 against the 17Bx16 mixture of experts’ 0.710) (Khatri et al. 2025). The takeaway is to compare recipes by their fitted ceilings rather than by which one is ahead at a given step.
A second pattern concerns data, and it cuts against intuition from pretraining: RL needs remarkably few distinct problems. Across Qwen2.5 models from 0.5B to 72B, Tan et al. found that test error follows a power law in compute. They then simulated a data-constrained regime on the 7B model, with fewer distinct problems than the run needs, by holding the number of training steps fixed and shrinking the pool of distinct problems, cycling through the smaller pool more times. Test performance barely changed with each problem repeated up to 25 times, and clear overfitting appeared only at 100 repeats (Tan et al. 2025). The extreme case is a single problem: RLVR on one example, duplicated to fill each batch, lifts Qwen2.5-Math-1.5B from 36.0% to 73.6% on MATH-500, the same score as training on 1,209 examples (Wang et al. 2025). On-policy distillation shows the same effect for a clearer reason. There, one prompt recovers most of the gain from distilling on the full dataset, 87% after 300 steps and 72% after 1,000, because the teacher grades every token the student samples: a single prompt, rolled out 64 times per update, yields tens of thousands of supervised token positions, and that signal persists after the student starts solving the prompt and is still useful on a prompt the student never solves,7 whereas an outcome reward gives nothing while every rollout fails and is exhausted once every rollout is correct (Fu et al. 2026). In both cases, the number of distinct prompts understates how much supervision a run receives; what matters in RLVR is whether pretraining has left headroom and whether the training problems lie at the edge of the model’s competence (C. Zhang et al. 2025).
Open questions follow directly:
- How much of the asymptotic performance is set by the base model’s support, as the elicitation problem suggests, and how much by inefficiencies in training recipes?
- Do fitted curves transfer across model families and task mixtures?
- How should a fixed budget split between pretraining, SFT, and RL?
- Does prolonged RL erode the plasticity it relies on (Dohare et al. 2024)? Plasticity is not the entropy collapse of Section 11.3: entropy measures how spread out the policy’s samples are, while plasticity measures how easily further training can still change the model. There is little direct evidence for LLMs. ProRL periodically resets the reference policy of its KL term to a recent snapshot, and the optimizer state, when runs stop improving, whereas vanilla GRPO keeps the reference fixed (Liu et al. 2025), and DeepSeek-V4.1-Flash merges checkpoints to reinitialize successive RL runs and extend RL compute beyond a single run (DeepSeek-AI 2026). Both are ways of rejuvenating a run that has plateaued, which implies adding back plasticity, but neither measures that value, since there is no agreed-upon definition of it.
There is little published work on the frontier regarding the science of RL compute, even though that is where the compute is. SemiAnalysis’s model of OpenAI’s total capacity has training and inference both growing steeply through 2030, and most of that training compute is now RL. Kimi K3, DeepSeek-V4.1-Flash, and the MiniMax-M2 series report RL results but no RL compute totals, so we can only look one level down at OLMo 3, whose 32B Think RL run took ~five days and 750 steps, and a continuation ran 21 more days to 2,300 steps with performance “not yet fully saturated” (Team OLMo et al. 2025). No published scaling law covers multi-domain, agentic, million-token RL, which is where the frontier labs now spend their RL compute.
11.6 Credit assignment at horizon scale
Research question. How does terminal outcome learning signal diminish on increasing horizons, and how can process-level signals be made scalable?
Credit in reasoning RL spans one generation of 500-30K+ tokens; agentic RL spans tens to hundreds of turns and 100K to 1M tokens, where a single episode-level scalar becomes increasingly uninformative. Karpathy’s phrase for this, quoted in Chapter 2, is “sucking supervision through a straw”: one number at the end of a rollout decides whether everything in it is upweighted or downweighted (Patel 2025). Intermediate verification, while possible in math, is rarely possible for agents, and the methods literature has no shared benchmark for comparing credit-assignment quality (Zhang 2026). Let’s not forget the well-known METR measure of the length of software tasks that frontier models complete at 50% reliability, which doubled roughly every seven months from 2019 to 2025 and has doubled roughly every three months since 2024 (Kwa et al. 2025; METR 2026b). The measure is now at its ceiling: only 5 of its 228 tasks are estimated to take a human 16 hours or longer, so METR treats horizons above 16 hours as unreliable, and an early version of Claude Mythos Preview, evaluated in March 2026, was already estimated at “at least 16hrs” (METR 2026a).
MiniMax states that outcome rewards alone “are insufficient for credit assignment” on trajectories of up to 192K tokens. It adds dense per-step process rewards, which penalize language mixing and malformed tool calls and reward well-structured intermediate reasoning, and computes each step’s advantage from the reward earned from that step onward against a trajectory-level baseline, even when the agent has truncated or rewritten its context mid-episode (MiniMax 2026). Judging from the examples MiniMax gives, these process rewards grade the form of each step rather than its contribution to the outcome, so which step actually solved the task is still left to the outcome reward. The other lever is the context the policy sees, which is also where academic work on long horizons is most active. Context folding, for example, trains the agent to collapse each finished sub-task into a short summary, rewards it for folding well, and matches a full-context agent while keeping an active context ten times smaller (W. Sun et al. 2025). Folding shortens the stretch of tokens across which one outcome reward must be spread, so better context management is, in part, better credit assignment.8
11.6.1 What is open
Whether outcome rewards, form-level process rewards, and context management suffice as horizons keep growing is open, and so is which intermediate states are verifiable.
11.7 Rewards beyond verification
11.7.1 How far can RLVR’s recipe extend into tasks with no checkable answer?
- Rubrics. Instead of asking a judge for one overall score on a 1-to-10 scale, a rubric reward gives the judge a list of criteria to check written for the specific prompt, with possibilities for the reward being a weighted sum over each criterion, or one overall score (Gunjal et al. 2025). At the frontier, Kimi K3’s judge writes a rubric for each task, as Table 9.2 shows (Kimi Team 2026).
- Reference likelihood. Where a reference answer exists but no checker does, the policy’s own probability of producing the reference can serve as the reward, with no verifier at all (Yu et al. 2025).
Rubric rewards are hackable in the ways Section 11.4 describes, and they cost a judge call per rollout. The open problem is not whether these signals work early in training, since they do, but whether they stay aligned with the target under the optimization pressure that frontier RL applies.
11.7.2 How much of what RLVR learns on checkable tasks transfers to the rest?
Jason Wei’s rule says which tasks RL improves directly; if RL on math and code taught general reasoning, verifiable domains might be enough. Across more than twenty open reasoning models, most gains in math fail to transfer to other domains, but in a controlled comparison on Qwen3-14B, math-only RL carried its gains over to other reasoning and even non-reasoning tasks, while math-only SFT gained less on other reasoning and fell below the base model on non-reasoning tasks (Huan et al. 2025). RL’s Razor: Why Online Reinforcement Learning Forgets Less argues that at matched performance on a new task, RL forgets less of what the model could do before than SFT does, because on-policy updates stay closer to the base model in KL (Shenfeld et al. 2025). Of six domains tested at 7B and 32B, math, code, and science (all common in pretraining data) benefit from each other, while logic, simulation, and tabular reasoning need in-domain data; whether larger models close that gap on their own is untested (Cheng et al. 2025). So RL on verifiable reasoning does transfer, but mainly between domains the base model already knows well; domains like logic, simulation, and tabular reasoning can still be improved directly, as Wei’s rule predicts, once they have verifiers of their own.
11.8 Self-improvement without external verification
Research question. Can a model’s own signals sustain RL improvement, or do self-reward loops inevitably collapse?
Consider evidence that supports the pro-self-improvement camp: majority vote over the model’s own samples, used as a pseudo-label on unlabeled test problems, raised Llama-3.1-8B-Instruct’s pass@1 on MATH-500 from 48.6% to 63.7% (Zuo et al. 2025). Given this result, one might conclude that these approaches should be scaled to frontier models.
It’s not all fun and games, though, because prolonged RL with majority-vote rewards leads to reward hacking and “sudden and complete performance collapse” (Shafayat et al. 2025). Internal-feedback rewards help base models early, then degrade performance below the starting model, and give little benefit to instruction-tuned models (Y. Zhang et al. 2025). A reward that confirms the model’s current beliefs drives entropy down, and pass@k falls with it (Zhou et al. 2025); this answer is refreshing because it’s a training problem which we can directly answer with complete certainty as a structural collapse in entropy.9
Self-improvement is governed by the generation-verification gap, i.e. how much better a model is at checking an answer than producing one (Song et al. 2024). A self-reward loop can only climb while the model’s own judgments are better than its answers; as you optimize against those judgments, the model’s answers will become as good as its judgments, and then there is no longer any leverage. In offline iterative self-improvement, the gap fell close to zero after two or three rounds, whatever the model’s size (Song et al. 2024). Training on intrinsic rewards raises performance and then lowers it, even as the intrinsic reward itself keeps rising, with the timing set by how well the model’s initial confidence tracks correctness, and one early warning sign has been found: the accuracy of self-generated pseudo-labels10 declines before performance does (He et al. 2026; Wang et al. 2026).
11.9 Models that write their own tasks
Research question. Can the model generate the environments and verifiers it trains on?
In Absolute Zero, one model proposes coding tasks, a code executor validates them, and the same model learns to solve them, reaching state-of-the-art results at 7B without in-domain data (Zhao et al. 2025). SPADE, whose authors include Absolute Zero’s first author, goes further: instead of single problems, the model writes complete multi-turn environments as executable code, with state, rewards, and verification, and the environment designer is rewarded for environments at the edge of what the agent can do, measured by how much a privileged hint raises the agent’s reward. The hint is the designer’s own, written by the same model, and serves only that reward. The external input that keeps the designer from collapsing is a seed document: SPADE seeds each environment with a document sampled from a pretraining corpus, and without it the designer produced one rotating-maze environment 41 times in a row. Think of the corpus as analogous to the real workflows that DeepSeek brought into its environment creation pipeline to preclude model collapse (Section 10.8). At 30B parameters, SPADE beats the strongest fixed-environment baseline by 5.3 points on average across eight held-out benchmarks, and its authors note a version of the leash that Section 11.3 describes: the designer cannot write environments more complex than its base model can express (B. Liu et al. 2026). When the proposer is rewarded for difficulty, it learns to hack that reward too, drifting toward artificially complex problems that teach nothing, such as theorem statements padded with long chains of “or” clauses (Bailey et al. 2026). The most contrived examples are large multiplication or problems which involve a random number generator, which, by design, can only be solved 50% of the time. A method called Self-Guided Self-Play counters this with a “guide”, a frozen copy of the initial model, that scores each proposed problem by its relevance to unsolved target problems and by how clean and natural it is You should see that this is congruent with the Spade work where they said that the designer can write environments no more complex than the base model. (Bailey et al. 2026). The pattern one notices in self-play is the necessity of grounding; one final example is formal program verification, where the formal verifier makes the gains possible (Wilf et al. 2025).
As Section 10.8 describes, DeepSeek-V4.1-Flash treats a task as a problem, an environment, and a verification system, and trains the model to build better tasks using difficulty and correctness as rewards, noting that this capability “remains far from perfect” (DeepSeek-AI 2026).
If the verifier matters more than the optimizer, and the model writes the verifiers, then verifier quality becomes a training target, and every failure in Section 11.4 can now enter through the task generator as well as through the policy. Whether task generators can be audited as fast as they produce tasks is open, although frontier labs already run these systems behind closed doors. Anthropic runs an automated review of all environments before and during training runs, yet by spring 2026 it was producing RL environments “faster than our systems could vet them”, “reward hacks and misconfigurations started outpacing our ability to filter or fix them”, and in April it froze all changes to its production RL environments for roughly a month to overhaul the stack (Anthropic 2026a).11
11.10 The agenda at a glance
| Problem | Best current evidence |
|---|---|
| Elicitation or creation | Default RLVR sharpens; targeted recipes expand |
| Over-optimization of learned graders | Weak rubric verifiers diverge from judge panels; strong ones reduce but do not eliminate hacking |
| What the verifier misses | Audits find hackable tests and brittle checkers |
| Hacking generalization | Production hacks generalize; Hacker-Opus stayed grader-bound |
| Monitorability | Measurably lower at the 2026 frontier; length penalties reduce it |
| RL compute | Sigmoid fits predict single-recipe runs |
| Credit at long horizons | Trajectory-level rewards plus context management; MiniMax adds per-step format rewards |
| Beyond verification | Rubric rewards work and are used at the frontier |
| Self-reward | Early gains, then collapse |
| Self-generated tasks | Self-play and frontier task synthesis work with grounded checkers |
SFT lost 7 problems the base agent solved while gaining 3.↩︎
This is relatively speaking, since today both of these models are impotent.↩︎
This idea is similar to the concept of a sample versus population in statistics.↩︎
One eternity in AI time.↩︎
Anthropic reaches a similar conclusion by a different route. The Claude Opus 4.8 system card reports that a white-box probe found reasoning about the grader in the model’s activations, unprompted and never verbalized, in around 5% of sampled RL episodes, and offers this “as an indication that chain-of-thought alone may not be sufficient to allow robust monitoring of frontier models for grader awareness” (Anthropic 2026b).↩︎
Advantage normalization, length control, zero-variance filtering, the off-policy algorithm, the FP32 logit fix, loss aggregation, the prompt curriculum, and the loss function.↩︎
Really worth reading this paper.↩︎
A critical qualifier: this folding process can also have the opposite effect, erasing those tokens of the utmost importance to eliciting a trajectory’s success.↩︎
As opposed to an interpretability artifact, which might lead to hundreds of hypotheses.↩︎
The answers the model treats as ground truth for its own training, such as the majority-vote answer.↩︎
Imagine a company moving at the speed of Anthropic taking a month-long break to overhaul infrastructure, they must have redone everything from scratch.↩︎